
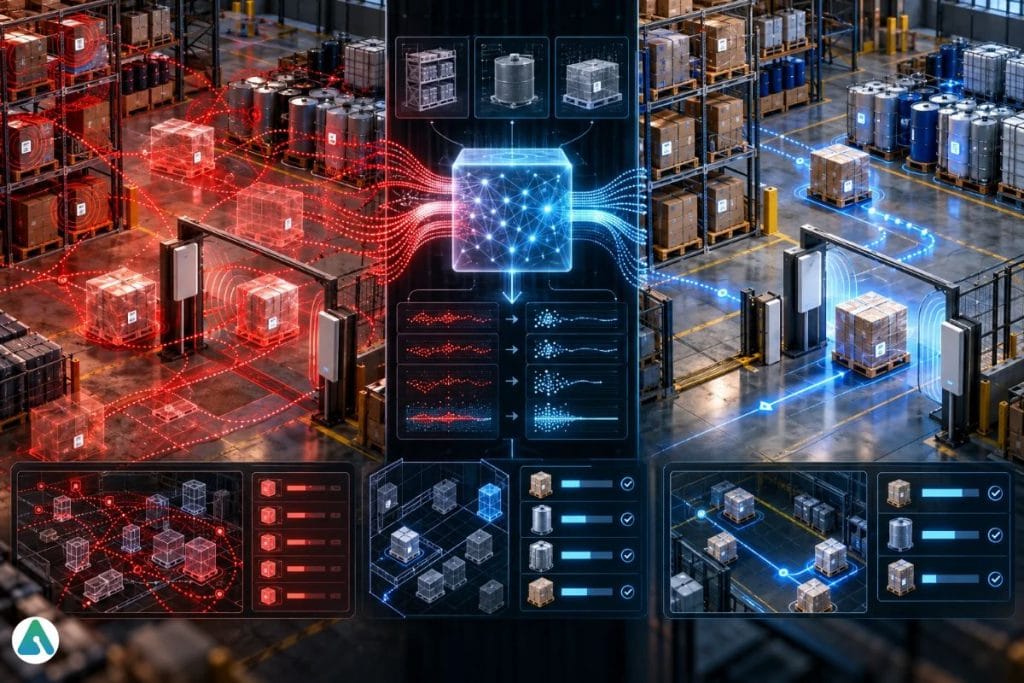
Seventy percent. That’s the read rate I watched a warehouse manager brag about in 2019, right before his team went back to clipboards. The hardware worked fine. The software drowned him in duplicate reads, ghost reads, and pallets that showed up in three rooms at once. So he quit.
That story is why I’m skeptical every time someone tells me tracking technology just got smarter. Usually it didn’t. What changed recently is narrower and more interesting: the software finally learned to clean up after the hardware. That shift is worth understanding, because if you’re the person responsible for knowing where your stuff is, it changes what you should buy and what you should expect.
Here’s the plan. We’ll cover why radio frequency identification frustrated so many teams for two decades, what machine learning actually fixed, a simple test I call the Three-Room Trial, and the mistakes that still sink rollouts today.
Why did RFID fail so many companies in the first place?
The physics were never the problem. Radio waves bounce off metal shelving, get absorbed by liquid, and spill past the dock door into the next aisle. A reader doesn’t know the difference between a tag on your pallet and a tag on a truck passing outside. So it reports everything.
Researchers studying distribution centres catalogued the same causes I kept seeing on site. Metal objects and the truck itself create multipath reflections that extend read range past where anyone intended. A worker parks a tagged item near the portal for a minute. Someone walks past the gate carrying something else entirely. Every one of those becomes a read.
Early software treated every read as truth. One tag crossing four readers in ninety seconds became four events. Your inventory report says you have four of something when you have one. Multiply that by ten thousand tags a day, and the report becomes noise, and a noisy report is worse than no report, because people trust it right up until it burns them.
Standards bodies saw this coming. GS1 built the numbering and data structures that keep tags from colliding with each other at the identifier level, and that work made interoperability possible. But a clean identifier on a tag doesn’t tell your system whether the read was real. That last mile was always a software problem wearing a hardware costume.
I’ve sat through enough demos to say this plainly: most failed deployments I’ve seen weren’t buying the wrong tags. They were buying software that couldn’t say “I don’t know.”
What machine learning actually fixed
Modern systems stop asking “did we see this tag?” and start asking “how confident are we?” That’s the whole trick, and it sounds small until you see it working.
Models trained on read patterns learn that a tag seen once by the far reader at 2:14 a.m. with a weak signal is probably spillover. A tag seen by three readers in sequence over eight seconds, each with decent signal strength, is almost certainly moving along a real path. The system assigns probability instead of certainty, and then it acts accordingly.
The research backs this up more concretely than most vendor decks do. One study applying machine learning to false-positive detection reported around 93% average accuracy, working from signal strength and timestamp features rather than treating each read as a discrete fact. Another, combining outlier detection with a random forest classifier, reached just over 94% on identifying whether a tag was genuinely moving through a gate or merely loitering near one.
Here’s the part vendors leave out. Most of that work was published between 2017 and 2019, using fairly ordinary classifiers. The technique isn’t new. What changed is that it finally shipped inside products you can buy, rather than sitting in papers nobody in operations reads.
Two practical consequences follow from how these models learn.
First, they need your building. Research on probabilistic approaches found that methods depending on rich prior knowledge perform poorly on small datasets, which is exactly why these platforms sharpen after a few months rather than a few days. Your aisles, your racks, your forklift traffic all become training signal. The National Institute of Standards and Technology has published extensively on how representative data shapes machine learning performance, and a warehouse is about as site-specific as data gets.
Second, where the model runs matters. Scoring reads close to the readers rather than in a distant cloud keeps decisions fast and keeps the system working when connectivity drops, which is the same argument driving edge computing across industrial deployments generally.
What does that buy you in practice? Fewer false alarms, so your team stops ignoring alerts. Better cycle counts, so you’re verifying sections of the warehouse instead of shutting down for a full physical inventory. And honest confidence scores, so when the system says a pallet is in Bay 4, you can act on it without walking over to check.
That alert fatigue point deserves emphasis. The same dynamic shows up wherever automated inspection lands: AI vision systems only deliver value once the false alarm rate drops far enough that operators still read the alerts on hour three of a shift.
The Three-Room Trial: how to test a system before you commit
Vendors will show you their best case. Your job is to build a small, mean test that reflects your worst case. Here’s the version I recommend, and it takes about three weeks.
Pick three spaces that misbehave differently. One room with metal shelving, one with liquid or dense product, one with a doorway where traffic passes close by. If your facility doesn’t have all three, simulate the hardest one.
Tag fifty real items, not demo items. Use the actual containers, the actual pallets, the actual tote bins. Demo tags on clean cardboard make everyone look like a genius.
Move things the way your team actually moves them. Don’t stage a tidy test. Let the normal shift run, including the sloppy parts, like the guy who parks a pallet in the walkway because he’s coming right back. The research literature lists exactly that behaviour as a known cause of false reads, so make sure your trial contains it.
Log every discrepancy by hand for one week. Yes, by hand. This is the part vendors hate, because it gives you ground truth to compare against their dashboard.
Ask for the confidence scores, not just the answers. If a system can’t tell you how sure it is, it hasn’t solved the original problem. It has just hidden it behind a nicer screen.
The point isn’t to find a system with zero errors. Nothing hits zero, and published accuracy figures cluster in the low nineties under controlled conditions rather than in the field. Treat any vendor quoting better than that with the scepticism you’d apply to any headline AI number. The point is to find a system whose errors you can predict, because predictable errors are manageable and random ones are not.
The mistakes that still sink rollouts
I’ll be blunt about the most common one: treating this as an IT project. It isn’t. It’s an operations project that happens to involve radios.
The teams that succeed put a floor supervisor in charge of the rollout and give them authority to change physical layouts. They move a rack six feet, they stop parking forklifts in a read zone, they put a shield on one reader. Antenna placement research found that setup changes alone significantly improved what the classifiers could achieve, which means the physical work multiplies the software work rather than competing with it. None of that shows up in a demo, and all of it decides whether your read rates hold on a busy Tuesday.
The second mistake is chasing perfect coverage everywhere at once. Start with the twenty percent of your inventory that causes eighty percent of your headaches. High-value tools, items that walk off, anything your finance team asks about every quarter. Prove the value there, then expand. I’d rather see a tight deployment in one building than a sprawling one nobody trusts.
The third mistake is ignoring the people scanning. If the new process adds a step for them and removes none, they’ll work around it within a month. Whatever you buy, make sure it takes something off their plate, not just adds visibility for management. Visibility nobody on the floor benefits from is a report, not a system.
Done well, RFID tracking stops being a gadget line item and starts being the reason your quarterly count takes an afternoon instead of a weekend.
The honest bottom line
The technology didn’t suddenly become magic. The software got better at handling messy reality, and that’s a less exciting story with a much bigger payoff. If you’ve been burned before, your skepticism is earned and useful. Bring it to the demo.
Run the Three-Room Trial. Insist on confidence scores. Put an operations person in charge. Then decide.
And if a vendor tells you read accuracy won’t be an issue, ask them what their error rate was at their last metal-shelf site. The pause that follows tells you everything.
Related: AI Vision vs RFID? Why Smart Warehouses Are Combining Both in 2026
