What Is the Smartest AI in the World in 2026? Top Models Ranked
No single AI wins everything in November 2026; the right pick depends on whether you value deep reasoning, low spend, human polish, or autonomous code. Claude Fable 5.2 tops composite reasoning. GPT-6.2 Astra dominates science, 3D, and robotics at about one-sixth of Fable’s average task bill. Gemini 4 Carbon still wins blind human preference, although Google’s newer Gemini 4 Neon now outscores it for less money. GitHub Copilot Fusion, a router across several models, sets the pace in terminal coding.
Two buyer rules cut through the noise. Subscribers should weigh usage allowances above token prices, and enterprises should weigh data-retention terms above a two-point index gap.
Part 1 explains how to judge any ranking, including six areas no leaderboard covers. Part 2 delivers the November snapshot, current picks and answers to the questions people ask most, such as the smartest AI for free, for coding, on Reddit, and by IQ.
Why do rankings and real-world performance diverge?
Each benchmark grades one narrow slice: a composite index scores fixed problems, an arena records taste, and a coding board rates complete agent setups. Stacking those slices into a single ladder mixes unlike things, and labs also tune toward public exams, so a leaderboard position reflects exam behavior more than your workload.
Measurement
Example
What it captures
Composite reasoning
Artificial Analysis Intelligence Index
Results across a chosen set of evaluations; primarily text and English
Human preference
Arena text voting
Which answer blind voters like more
Agent coding
Terminal-Bench 4.1
How well a model plus its harness finishes terminal work
IQ-style puzzles
Mensa Norway quiz
A narrow set of visual pattern puzzles
Community opinion
Reddit threads
Individual day-to-day experience
Voters reward tone, formatting and confidence, so a fluent wrong answer can beat a clumsy right one. Arena’s style controls narrow that bias without removing it, and a workflow that demands strict instruction-following over polish will find crowd-voted Elo misleading. AI video model rankings show the same divide, with prompt adherence and crowd taste pointing at different winners.
Goodhart’s law explains the second distortion: once a score becomes the goal, it stops measuring what it measured. Anthropic’s November 9 system card for Fable 5.2 adds evaluation awareness, reporting that the model often recognizes tests, so its alignment results may not fully predict deployed behavior.
Takeaway: use any leaderboard as a shortlist filter. A model that suspects an exam can act differently on real work, which makes a trial on your own material the only deployment evidence that counts.
Versions matter as well. Artificial Analysis launched index version 5 in late October and patched it to 5.0.1 on November 2, so compare numbers only within one version.
Is the reasoning-effort dial worth paying for?
Rarely at the top setting. A task’s bill equals tokens written times token price, and a model that thinks longer writes more tokens. Fable 5.2 and GPT-6.2 Astra carry identical base rates, $8 per million input tokens and $40 per million output tokens, yet Fable’s average bill runs more than six times higher because it writes roughly seven times the output (derived from Artificial Analysis’s time per task multiplied by output speed).
The efficient picks sit lower on the dial. Artificial Analysis’s Astra versus Fable breakdown covers every level (figures from November 20):
Configuration
Index
Cost per task
Time per task
GPT-6.2 Astra, medium
57
$1.62
about 4.7 minutes
Claude Fable 5.2, low
54
$3.10
about 5.5 minutes
Gemini 4 Neon, xhigh
61
$6.44
about 21 minutes
Max buys Fable eight extra points over Astra’s medium level at sixteen times the spend.
Speed needs its own explanation. Fable streams about 110 tokens per second against Astra’s 49, yet it needs 41.7 minutes per index task to Astra’s 14.1, roughly triple, because it reasons through so many more tokens. One question at max still wraps up in about seven minutes on both (413 seconds versus 445), so the gap shows up on multi-step jobs. A fast streamer can feel sluggish once it starts thinking at length.
Pricing quirks tilt the math further. A cache read costs $0.20 per million tokens on Fable and $0.40 on Astra, which favors long agent sessions that keep re-reading the same files, a detail that has shaped this rivalry since the earlier Astra versus Fable 5.1 matchup. And identical base rates don’t guarantee identical bills on huge prompts: GeoToolbox reports that OpenAI surcharges Astra past 272,000 input tokens, while Anthropic bills Fable’s entire 1M window at standard rates.
Is the best coding AI a model at all?
Increasingly, no. The strongest coding results now come from harnesses, the scaffolding around a model, and from routers that coordinate several models. Artificial Analysis’s coding-agent pages compare one model across different harnesses because identical weights behave differently in each.
A harness controls how context gets compacted or pruned, how shell commands run in a sandbox, how failed steps retry, and when sub-agents spawn. As raw model quality converges, that scaffolding separates the winners.
GitHub’s Copilot Fusion announcement shows the router approach through three execution patterns. Single hands the job to one model. Cascade lets an efficient model draft while a quality gate decides whether to accept that draft or escalate to a stronger one. Critique has one model draft, a second review, and the first revise. Cascade and Critique add review passes, so they run slower and can drain credits on hard prompts.
Developers building their own routers choose among agentic frameworks such as LangGraph and CrewAI. SWE-bench Verified no longer separates the frontrunners, since top results cluster too tightly, so harder suites like SWE-bench Pro carry more weight.
What do the leaderboards still miss?
The index tables grade text reasoning, coding, and professional work. Six areas fall outside them.
Honesty under uncertainty
Smart and reliable are separate columns. Artificial Analysis’s AA-Omniscience, one of the nine index evaluations, rewards correct answers, penalizes confident wrong ones, and doesn’t penalize abstaining. Fable 5.2 at max tops its net score at 67, while Gemini 4 Carbon at medium posts the lowest hallucination rate on the current chart, 4%. A strong reasoner can still guess where a more cautious model would admit it doesn’t know.
Long-horizon execution and context
A Long-Horizon-Terminal-Bench 2.0 study found frontier models still struggle with sustained work; the best, GPT-6 Astra, resolved 48.1% of tasks at its strict threshold, though that study predates GPT-6.2. Both Fable 5.2 and Astra offer windows of roughly 1M tokens, yet window size doesn’t establish how accurately a model uses every passage.
Refusals
OpenAI shipped the original GPT-6 Astra as its first model rated Critical for cyber capability, according to NYU Shanghai’s RITS summary. Strict safeguards can stall legitimate security testing or dual-use code. Artificial Analysis has added a Safety Refusals section to its coding-agent pages, but the index tables don’t carry it, and for technical teams that false-alarm frequency can outweigh a two-point gap.
Modalities: voice and computer use
Artificial Analysis describes its index as primarily text and English, and benchmarks visual reasoning, speech and multilingual performance separately. Its pages list text and image input for both Fable 5.2 and Astra, while Gemini 4 Neon also accepts speech and video. Anthropic positions Fable for computer use and long-horizon research, yet no table here scores either skill or long-term memory directly.
Data terms
Enterprise buyers often decide on retention, not points. Anthropic’s Fable-class models, documented for Fable 5 and 5.1, require 30-day data retention with no standard zero-retention option, though the company later added an Enterprise Frontier Safeguards route for approved customers, per Anthropic’s support pages and The Register. On Amazon Bedrock, Fable requires opting into AWS’s provider data-sharing mode. Teams that give agents repository or cloud access should also restrict permissions, as guidance on controlling what agents can access explains.
Self-hosting friction. Open-weight models save token spend but demand GPU capacity, and shrinking them through quantization can cost accuracy, so the sticker savings narrow once you run them yourself.
Can AI models score higher than humans on IQ tests?
On public Mensa-style puzzles, top models now hit the ceiling, yet an AI has no clinically established IQ. IQ is a percentile against a human norming sample, and a model has no such sample behind it.
TrackingAI runs the Mensa Norway quiz on dozens of models weekly, and 36Kr reported frontier models reaching the paper’s maximum in late September. Contamination clouds the picture, because models may have trained on the published questions. A 2024 offline quiz that never appeared online cut some models’ scores by more than 20 points, while the best stayed near the top. Per-model IQ numbers are excluded here for that reason: matching familiar patterns isn’t the same as reasoning.
Artificial Analysis Intelligence Index v5.0.1, nine evaluations. Cost is the weighted average Artificial Analysis spent per index task at the listed reasoning level, far below the bill for running the whole index.
Model
Index
Reasoning level
Cost per task
Claude Fable 5.2
65
Max
$26.54
GPT-6.2 Astra
62
Max
$4.00
Gemini 4 Neon
61
Xhigh
$6.44
Gemini 4 Carbon
60
High
$7.76
Claude Opus 5.5
59
Max
$10.04
Other standings, each with its own date and method:
Claude Mythos 5.2 outclasses these models in raw capability, but Anthropic keeps it behind cybersecurity and life-sciences verification programs, so the tables cover only what ordinary users can open.
What is the smartest AI in the world right now?
Claude Fable 5.2 ranks first on the Artificial Analysis Intelligence Index, three points ahead of GPT-6.2 Astra. Gemini 4 Neon and Gemini 4 Carbon trail by one and two points, and Fable also tops the Vals Index.
Google’s November 18 launch made the sharper story. Artificial Analysis says Neon scores one point above Carbon at about 17% lower cost and about 40% less time per task, so Google’s newer model undercuts its own flagship. Astra sits second by model, though it slides to third on the raw list because Artificial Analysis gives each reasoning level its own row.
Which AI should you pick for your work?
Start with the job, then weigh access, speed, and price. Save the highest-rated model for work where mistakes are expensive, such as code, contracts, and analysis, and step down to lighter levels for drafts and brainstorming.
If you need
Start with
Why
The hardest long technical projects
Claude Fable 5.2
Highest index rating; costs twice Opus 5.5’s token price
Scientific, 3D or multistep professional work
GPT-6.2 Astra
Tops Terminal-Bench-Science, AA-3D and OpenAI’s professional exam
Finance-heavy agent work
Gemini 4 Carbon
Heads the Vals Finance Index
A daily default
Claude Opus 5.5
Anthropic’s suggested starting point, per TechJack Solutions
Strong reasoning for less
GPT-6.2 Sol or Gemini 4 Neon
Near-flagship results at a fraction of the spend
Coding inside GitHub
Copilot Fusion
Highest Terminal-Bench 4.1 entry
High volume at low cost
Hydrogen, or open-weight models such as Kimi K3.1 Pro
Far lower spend per task
Fewest confident wrong answers
Gemini 4 Carbon
Lowest hallucination rate on the current AA-Omniscience chart
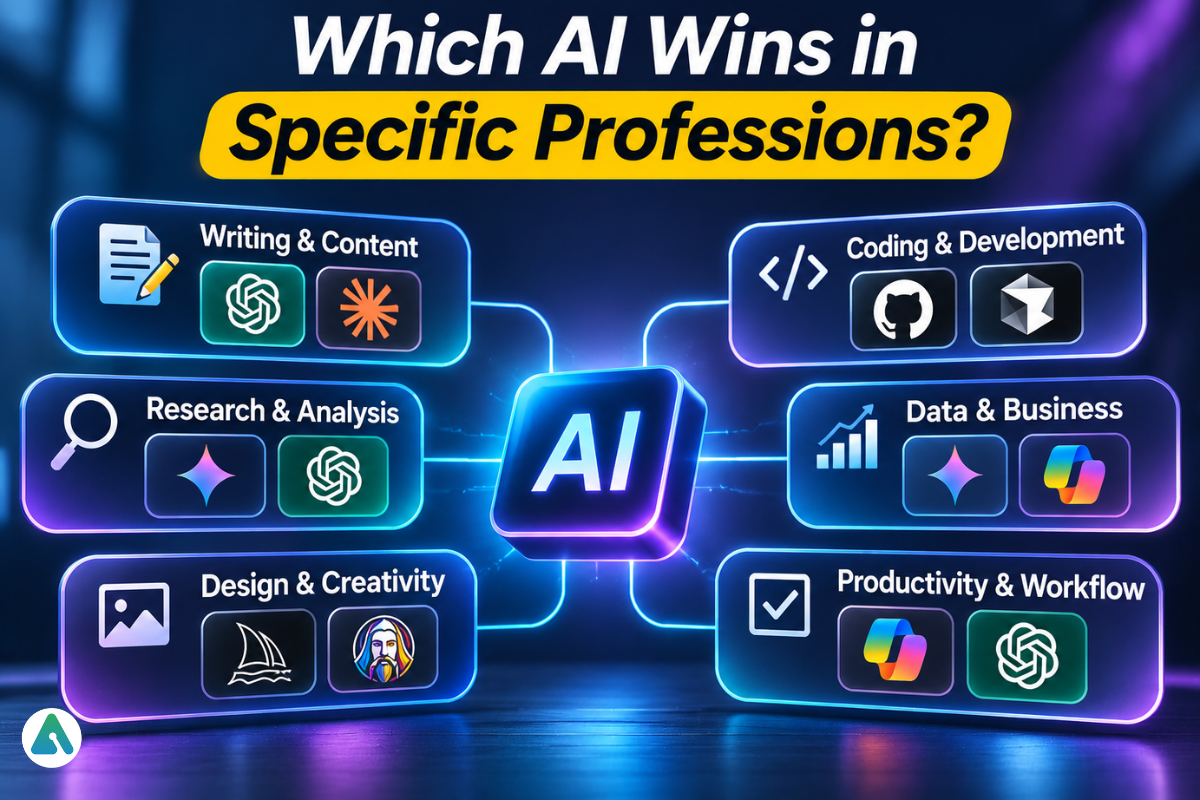
The composite index hides field specialists. Astra tops OpenAI’s own professional-work exam, while a finance, coding, legal, and tax composite places it seventh, so the “best” model depends on whose exam you read.
Test
Result
Source type
Agents’ Last Exam v1.1
GPT-6.2 Astra 78.3%; GPT-6 Astra 73.1%; Claude Fable 5.2 72.8%
OpenAI-reported
Vals Finance Index
Gemini 4 Carbon at 67.05%
Outside evaluator
Vibe Code Bench 1–100 (a separate Vals coding test from the one inside its index)
Astra 55.16%; Gemini 4 Carbon 49.73%; GPT-6.2 Sol 40.94%
Outside evaluator
FrontierCode 2.0 (maintainer-graded changes)
Fable 5.2 (xhigh) 50.2% at $17.73; Opus 5.5 47.3% at $12.82; Astra 44.2% at $5.97; Sol 43.8% at $1.29; Carbon 42.6% at $5.06
Outside evaluator
Vals weights each field by its share of US GDP, whereas Artificial Analysis blends nine evaluations, so neither ranking overrules the other. Choose the one that mirrors your field.
Which AI codes best right now?
GitHub Copilot Fusion posts 71.2% (±2.9) on the Terminal-Bench 4.1 table as mirrored by Snorkel AI, for about $2,000 in total run cost. Claude Opus 5.5 in Claude Code posts 65.8% for about $4,700. Google says Gemini 4 Neon reaches 65.2% on the same table.
A second measurement tells a different story, so keep the two apart. In Artificial Analysis’s Coding Agent Index v2.0, built on Terminal-Bench 4.0, Fusion at max costs $5.59 per task against $11.42 for Claude Code with Opus 5.5 at max, while landing two points lower. GitHub also runs a limited-time 30% discount on model costs inside Fusion, which holds November spending below normal rates.
GPT-6.2 had a rougher coding debut. Artificial Analysis found Astra flat against GPT-6 Astra on the Coding Agent Index, and Sol fell three points from GPT-6.1 Sol. GPT-6.2 Sol has no Terminal-Bench 4.1 entry yet.
Is ChatGPT still the smartest AI, and do subscription limits matter more than model rank?
ChatGPT still draws the largest audience but doesn’t hold the top reasoning position. The Pew Research Center’s February 2026 survey found it the most-used chatbot among U.S. adults, and Edison Research at SSRS put weekly AI use among American adults at 65% in May, up from 52% in February.
For readers on $20 to $200 monthly plans, allowances outweigh token prices. OpenAI’s release notes say Work and Codex share one usage pool, and Online Tech Tips reports that Ultrafast mode drains it quicker. Plus includes only a limited Astra allowance, with extra credits for sale. Wharton’s Ethan Mollick found Astra 6.2 harder to steer than rival models, per Implicator. Before upgrading a tier, work out whether your bottleneck is model intelligence or session limits.
That split also explains why agents differ from chatbots: a chatbot answers while an agent finishes the job, and users judge each by different failures. Claude suits long writing and technical work, ChatGPT carries the widest feature set, and a September Gemini versus ChatGPT comparison frames Google’s pull around Workspace tools.
What is the smartest AI for free?
Free plans exclude every top-ranked model. They run lighter engines that vendors rotate often, so verify each plan’s current lineup before relying on it.
Plan
Models you get
Notes
ChatGPT Free
GPT-5.6 Luna, with a Think button
Per OpenAI’s help center
ChatGPT Plus
Astra and Sol inside Work and Codex
Standard Chat tops out below Astra
ChatGPT Pro, Business, Enterprise
GPT-6 Pro (powered by Astra) in Chat
Enterprise and Edu admins must switch the models on
Claude paid plans
Fable 5.2 and Opus 5.5
Fable arrives on Pro, Max, Ultra, Team and Enterprise
Google
Hydrogen for everyday help, Neon for deeper analysis, Carbon for code and complex work
Carbon needs Google AI Ultra or the paid API
The best free AI is whichever one handles your chores inside its limits. Upgrade once those limits start blocking real work.
What about mid-priced and open-weight models?
Most professionals don’t choose between Fable and Astra; they pick from a cheaper tier. Claude Sonnet 5.5 scored 56 at launch but wrote the most tokens Artificial Analysis had measured, about 193,000 per task at max, which left it off the cost-efficiency frontier. GPT-6.2 Sol reaches 57 at about 15% of GPT-6 Astra’s cost per task, per Artificial Analysis, and Astra at high effort lands near 60 for roughly $2 per task. Gemini 4 Hydrogen lists at $1.50 and $7.50 per million tokens and ranks above Astra on the Vals Index.
Open-weight models have narrowed the gap on routine knowledge work. On the Vals Index, Qwen4-Max scores 63.20% and Kimi K3.1 Pro 62.52%, roughly five points behind Astra’s 67.66%. Kimi K3.1 Pro lists at $2 and $10 per million tokens and costs about $3.68 per index task. That trade suits drafting, summarizing and sorting, though Vals found Kimi K3.1 weaker than K3 on legal and tax work, and a lab’s self-reported coding numbers stay unverified until outsiders reproduce them.
Is Grok smarter than ChatGPT or Claude?
Not on current outside ratings. Grok 4.7 scored 46 on Artificial Analysis’s older index (version 4.3.2) at its September 21 launch, then 35 on version 5. The drop reflects a new evaluation suite, and the model itself didn’t regress.
Version 5 runs nine evaluations, including FrontierCode 2.0 and Terminal-Bench-Science, replacing a ten-evaluation mix, so scores across versions don’t line up. Grok does have strengths: it jumped 111 Elo points on Artificial Analysis’s long-horizon knowledge-work test and plugs tightly into X. It also writes far more output tokens than Grok 4.6, which raises running costs. Grok 4.8 hasn’t shipped.
What AI does Elon Musk use?
Musk runs xAI and promotes Grok, but no source documents indicate which assistant he uses privately. On November 10, 2026, Forklog reports, he posted that Grok 4.8 is not as good as Claude Opus 5.5, which he called “a masterpiece.” He added that Grok 4.8 has finished preliminary training and is in reinforcement-learning tuning.
Three separate things sit inside that story. His words are opinion, and his forecast that Grok 5 should surpass Opus 5.5 within two or three months came with no release date or test results. Outside ratings place Grok 4.7 below the frontrunners. And xAI’s newest shipped model is Grok 4.7. Praise for a rival doesn’t prove private use.
What does Reddit say is the smartest AI?
Reddit has no consensus winner. Tom’s Guide’s review of the discussion describes users abandoning the hunt for one tool that replaces the rest and matching a tool to each job instead, with many stacking several. It also notes that the QuitGPT movement sent users toward Claude and Gemini while ChatGPT stayed the most popular.
Community chatter captures daily friction that benchmarks skip, such as usage caps, context loss mid-thread, and shifts in tone, at the cost of small samples and brand loyalty.
How do you test an AI before paying?
Send the same five jobs to your shortlist: a reasoning puzzle, a research question, a coding fix, a long-document question, and a writing assignment. Log the model version, reasoning level, date, outcome, and bill. Every model still produces confident errors, so verify names, numbers, and quotes against sources.
FAQs
Q. Why does Gemini 4 Carbon cost more per task than Neon, and when do prices change?
Artificial Analysis prices Carbon at its standard $4 and $20 per million tokens, above Neon’s $3 and $15. Google’s introductory Carbon rate of $2 and $10 runs through November 30, so November bills come in below Artificial Analysis’s figure, and rates double on December 1.
Q. How do cache writes and context windows differ across the labs?
Anthropic charges $10 per million tokens to write a five-minute cache entry and $16 for a one-hour entry, against $0.20 for reads, on a 1M-token window. Carbon’s window also reaches 1M tokens. Astra’s long-prompt surcharge appears in the cost section above.
Q. How fast do these standings change?
Quickly. Fable 5.2 launched on November 9, Gemini 4 Carbon on November 10, GPT-6.2 Astra on November 17, and Gemini 4 Neon on November 18, and Artificial Analysis changed its index version in the same period. Re-check dates before acting on any single figure.
Disclaimer: AI rankings and benchmark scores change frequently. This article uses publicly available evaluations and research at the time of writing. Results may vary depending on the model version, testing method, and access plan.
Tags:
Sebastian Vale
Sebastian Vale reviews the latest AI tools and tech innovations, breaking down complex concepts into clear, actionable insights. He also creates step-by-step guides, helping readers make smarter decisions and stay ahead in a fast-moving digital world.